
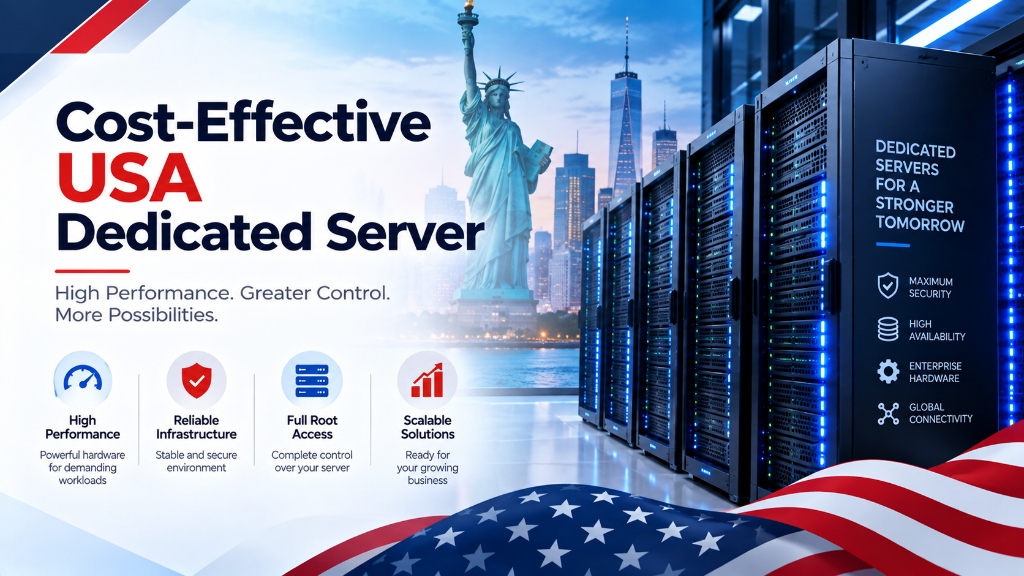
Deploying an enterprise USA Dedicated Server in certified Ashburn, Dallas & Silicon Valley data centers delivers direct local peering via Equinix & Any2Exchange, slashing latency for domestic visitors down to sub-15ms. Powered by dedicated AMD EPYC or Intel Xeon processors, unshared ECC RAM, and PCIe Gen4 NVMe RAID arrays, it provides guaranteed computing resources, regional data compliance, and 99.9% uptime for mission-critical digital workloads.
Explore our flexible VPS hosting plans for flexible virtualization.
- Low-Latency Interconnects: Direct routing through Equinix & Any2Exchange ensures deterministic response times across USA and neighboring markets.
- Enterprise Hardware Isolation: Dedicated CPU execution threads and PCIe Gen4 NVMe arrays eliminate noisy-neighbor bottlenecks.
- Regional Compliance & Security: Localized data residency with in-line DDoS mitigation and 24/7 proactive technical operations.
Enterprise IT infrastructure planning across North American data centers has undergone a fundamental architectural shift. Organizations managing high-throughput web platforms, real-time analytics engines, and high-concurrency database clusters are rigorously auditing total cost of ownership (TCO). While early cloud migrations promised operational elasticity, sustained high-utilization workloads on multi-tenant public cloud platforms frequently lead to exorbitant egress bandwidth fees, CPU throttling, and unpredictable monthly invoicing. To achieve sustainable cost efficiency without compromising enterprise reliability, infrastructure architects are deploying cost-optimized bare-metal infrastructure through an enterprise dedicated server engineered for compute density, high energy efficiency, and predictable line-rate networking. For mission-critical single-tenant workloads, deploy our high-availability cloud server infrastructure with unshared physical compute. For organizations scaling high-throughput compute workloads, our USA Dedicated Server Hosting infrastructure provides dedicated unmetered performance and enterprise hardware isolation.
A dedicated bare-metal server delivers unmetered hardware performance. Every physical CPU clock cycle, every gigabyte of DDR5 memory bus bandwidth, and every read/write IOPS of the NVMe array is permanently dedicated to your workload. For growing organizations expanding beyond entry-level VPS hosting or standard web hosting configurations, bare-metal server deployments replace volatile per-gigabyte cloud billing with predictable, fixed monthly operational expenses. When selecting a server administration interface, review our comprehensive Plesk vs cPanel control panel guide.
The Economics of Bare-Metal Infrastructure vs. Multi-Tenant Public Cloud
Total cost of ownership for server infrastructure encompasses physical capital, rack space, power utilization efficiency (PUE), transit commitments, and engineering operational overhead. Public cloud providers monetize compute, memory, disk IOPS, and network egress as separate billable items. When an application runs continuously at 60% or higher utilization, multi-tenant cloud instance pricing becomes substantially more expensive than dedicated bare-metal hardware.
In addition, premium United States data center facilities in Dallas, Ashburn, Chicago, and Los Angeles provide bulk 1Gbps and 10Gbps unmetered network ports. This connectivity model completely eliminates the risk of bandwidth bill shock during sudden viral marketing campaigns or high-volume data ingest cycles.
Consolidating multiple virtual machines onto a single high-density bare-metal platform enables organizations to reduce overall infrastructure expenditures by 40 to 65 percent while gaining complete hardware performance predictability.
Silicon Density Innovations: AMD EPYC Bergamo and Intel Emerald Rapids
The rapid advancement of x86 server microarchitectures has transformed compute density per rack unit. High-density server platforms enable organizations to consolidate dozens of older dual-socket machines into single 1U or 2U enclosures, drastically lowering data center rack footprint and power consumption costs.
Processors such as the AMD EPYC 9754 (featuring 128 physical Zen 4c cores and 256 execution threads per socket) offer unparalleled compute economics for microservice orchestration and containerized workloads. By packing dense, power-efficient execution cores into a standard socket envelope, engineering teams achieve massive parallel throughput without incurring the thermal and power penalties of legacy multi-socket server configurations.
Enterprise Hardware Efficiency and TCO Matrix
| Platform Class | Processor Model | Physical Cores/Threads | Memory Bandwidth | Storage Bus Throughput | Target Workload Profile |
|---|---|---|---|---|---|
| High-Clock Value | Intel Xeon E-2388G | 8 Cores / 16 Threads | Dual-Channel DDR4 (50 GB/s) | 2x 1TB PCIe 3.0 (3.5 GB/s) | Single-Threaded Apps, Light CMS |
| Balanced Enterprise | AMD EPYC 7763 | 64 Cores / 128 Threads | 8-Channel DDR4 (204 GB/s) | 2x 1.92TB PCIe 4.0 (7.0 GB/s) | Virtualization, High-Volume Web |
| Modern Flagship Density | AMD EPYC 9654 | 96 Cores / 192 Threads | 12-Channel DDR5 (460 GB/s) | 4x 3.84TB PCIe 5.0 (14.0 GB/s) | Kubernetes Clusters, Microservices |
| Data & Analytics Workhorse | Dual Intel Xeon Gold 6430 | 64 Cores / 128 Threads | 8-Channel DDR5 (307 GB/s) | 4x 3.84TB U.3 NVMe (10.0 GB/s) | PostgreSQL, Vector Search Engines |
Storage Architecture: Direct-Attached NVMe Solid-State Storage
Storage subsystem economics have shifted dramatically. While mechanical hard disk drives remain useful for archival data storage, enterprise SATA solid-state drives are no longer optimal for operational primary storage. Modern cost-effective dedicated server architectures incorporate U.2 and E1.S form-factor NVMe solid-state storage connected directly to CPU PCIe root complexes.
Eliminating proprietary hardware RAID controller cards and host bus adapters removes hardware licensing fees and architectural bottlenecks. Direct-attached NVMe storage configured with software RAID delivers exceptional endurance and sustained throughput at significantly reduced hardware acquisition costs.
Monitoring NVMe Health and Wear Telemetry via Linux CLI
Maintaining cost-effective infrastructure requires monitoring solid-state drive wear and endurance metrics to prevent unexpected drive failures:
Automating these checks through Prometheus Node Exporter allows engineering teams to identify deteriorating media early, maintaining maximum service uptime without purchasing expensive proprietary storage arrays.
Strategic Geographic Placement Across USA Data Center Hubs
The geographic location of your dedicated server infrastructure fundamentally dictates network transit latency and routing efficiency. In the United States, primary data center hubs provide distinct network peering advantages:
- Ashburn, Virginia: Known as Data Center Alley, Ashburn handles a vast percentage of global internet traffic. It provides unparalleled low-latency cross-connects to European trans-Atlantic subsea cables and tier-one peering points.
- Dallas, Texas: Serves as the premier central routing hub for North American traffic, achieving balanced 25-35ms latencies to both East and West coasts, as well as direct low-latency routes into Latin America.
- Chicago, Illinois: Provides low-latency fiber paths engineered for high-frequency financial platforms and Midwestern enterprise consumer bases.
- San Jose / Los Angeles, California: Primary landing hubs for trans-Pacific submarine cables connecting North America to East Asia, Japan, Singapore, and Australia.
Positioning bare-metal hardware within these strategic metro regions ensures optimal routing efficiency, reducing latency for customer-facing web platforms transitioning from basic virtualized instances.
Linux Operating System Sizing and Power Governors
Running bare-metal hardware efficiently requires tuning CPU power states and processor governors within the Linux kernel. By configuring the CPU frequency scaling driver appropriately, servers achieve maximum compute output during peak business hours while reducing unnecessary energy consumption during idle intervals: To achieve balanced multi-instance agility and cost efficiency, pair your deployment with USA VPS Server Hosting solutions featuring high-speed NVMe storage arrays.
Enabling the `performance` governor bypasses CPU frequency ramp-up latency, ensuring that transactional workloads receive instantaneous hardware responsiveness without clock-rate throttling.
Network Redundancy and BGP Route Optimization
A cost-effective USA server deployment must maintain carrier-grade network availability. High-volume dedicated servers integrate multi-homed BGP routing, blending bandwidth across Tier-1 carriers such as Lumen, NTT Communications, GTT, Telia (Arelion), and Hurricane Electric. Automated route optimization platforms continuously analyze transit packet loss and latency, dynamically steering traffic along the lowest-latency path.
Deploying Fair Queueing (`fq`) combined with Google’s BBR congestion control algorithm enables dedicated servers to achieve line-rate 10Gbps transmission speeds even across lossy or congested long-haul transit networks.
Hybrid Cloud Architectures: Interconnecting Bare-Metal with Public Cloud Direct Connect
Modern enterprise infrastructure strategies rarely rely on an absolute dichotomy between public cloud and bare-metal hosting. Leading organizations implement a hybrid deployment architecture: deploying high-volume, continuous database clusters and core API backends on cost-effective dedicated bare-metal servers, while utilizing public cloud providers solely for elastic burst capacity or specialized global SaaS integrations.
In premier carrier-neutral American data centers (such as Equinix Ashburn or Infomart Dallas), bare-metal servers establish private direct cross-connects (such as AWS Direct Connect, Azure ExpressRoute, or Google Cloud Interconnect) via 10Gbps dedicated fiber patch cables. This topology bypasses the public internet entirely, establishing private sub-2ms network tunnels between your high-performance bare-metal database and public cloud container clusters:
This hybrid architecture allows organizations to keep heavy, expensive, data-intensive workloads on predictable bare-metal silicon while retaining cloud elasticity for unpredictable, bursty edge workloads.
Automated Bare-Metal Provisioning via PXE, iPXE, and Cloud-Init
Managing bare-metal infrastructure at scale does not require manual OS installations or physical data center visits. Enterprise data centers automate bare-metal lifecycle management using Preboot Execution Environment (PXE) and iPXE network booting combined with cloud-init metadata automation:
Through infrastructure-as-code orchestration frameworks such as Terraform and Ansible, systems engineers can automate the complete server lifecycle: powering on the physical chassis via IPMI/Redfish, formatting NVMe arrays with software RAID 10, bootstrapping custom kernel parameters, and deploying production container orchestration fabrics within minutes.
Predictable Capacity Planning and Hardware Depreciation Lifecycle
Long-term infrastructure financial management requires comprehensive hardware lifecycle modeling. When organizations rent dedicated bare-metal servers under predictable multi-year or annual contract arrangements, operational expenditure remains completely flat regardless of customer traffic spikes or database query volumes.
Modern North American enterprise data centers are engineered around extreme Power Usage Effectiveness (PUE) metrics, frequently achieving PUE ratings between 1.10 and 1.18. High-efficiency redundant power distribution units (PDUs) and 80 Plus Titanium certified power supplies convert AC grid electricity to internal 12V DC server rails with greater than 96 percent efficiency. By combining efficient physical power conversion with high-density AMD EPYC silicon, modern bare-metal platforms drastically reduce thermal output per compute thread.
This thermal efficiency enables data centers to pass power savings directly to infrastructure clients in the form of competitive, unmetered bandwidth packages. Organizations avoid the variable surcharge models standard in public cloud platforms, where network transit, disk IOPS spikes, and memory allocations introduce sudden budget variances. Instead, engineering teams can forecast technical growth with precision, knowing their computational foundation can absorb sustained enterprise demand without financial volatility.
Frequently Asked Questions
Q:
How does bare-metal hosting reduce total cost of ownership compared to public cloud?
Q:
Which US data center location provides the most balanced nationwide coverage?
Q:
Why is direct-attached NVMe storage superior to traditional hardware RAID controllers?
Q:
Can modern high-core bare-metal servers replace virtualized infrastructure clusters?
Q:
What is the performance advantage of configuring the CPU scaling governor to performance?
Infrastructure Decision Framework: Choosing Your Deployment
Balancing low latency transit, dedicated hardware isolation, and predictable operating costs ensures long-term performance stability for enterprise applications.
Deploy high-performance enterprise dedicated server solutions equipped with enterprise NVMe storage arrays, redundant network uplinks, and 24/7 expert engineering support from Onlive Infotech.
For streamlined domain management and server configuration across multi-tenant environments, refer to our comprehensive Plesk vs cPanel hosting control panel guide.
•
✓
